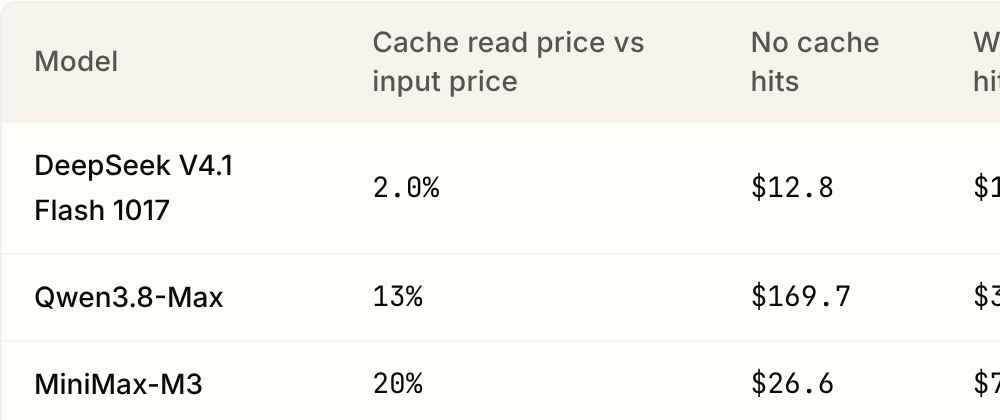
Prompt caching explained: how cache-hit pricing cuts your LLM billWhat the cache-read-to-input ratio is worth, how to structure prompts for hits, and how to read the counter.Nov 11, 2026 · 4 min read
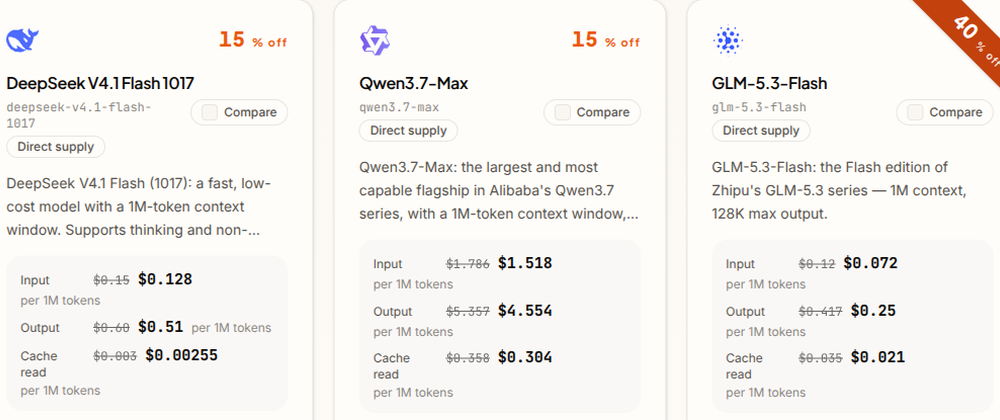
Nov 10, 2026Nov 10, 2026 · 2 min readCall DeepSeek, Qwen and GLM with one OpenAI-compatible API keySame OpenAI SDK, one endpoint: change the model name and keep your code.2 min read